Google AI Search Guidance: Evidence, Access and Usable UX
Google’s AI guidance prioritizes original evidence, indexed pages and usable journeys. Special AI files, forced chunking and inauthentic mentions do not replace those requirements.
Use Google's AI guidance to improve original evidence, technical access and task completion. It does not require a separate set of files, tiny content blocks or artificial brand mentions to enter AI Overviews and AI Mode.
Eligibility and source retrieval
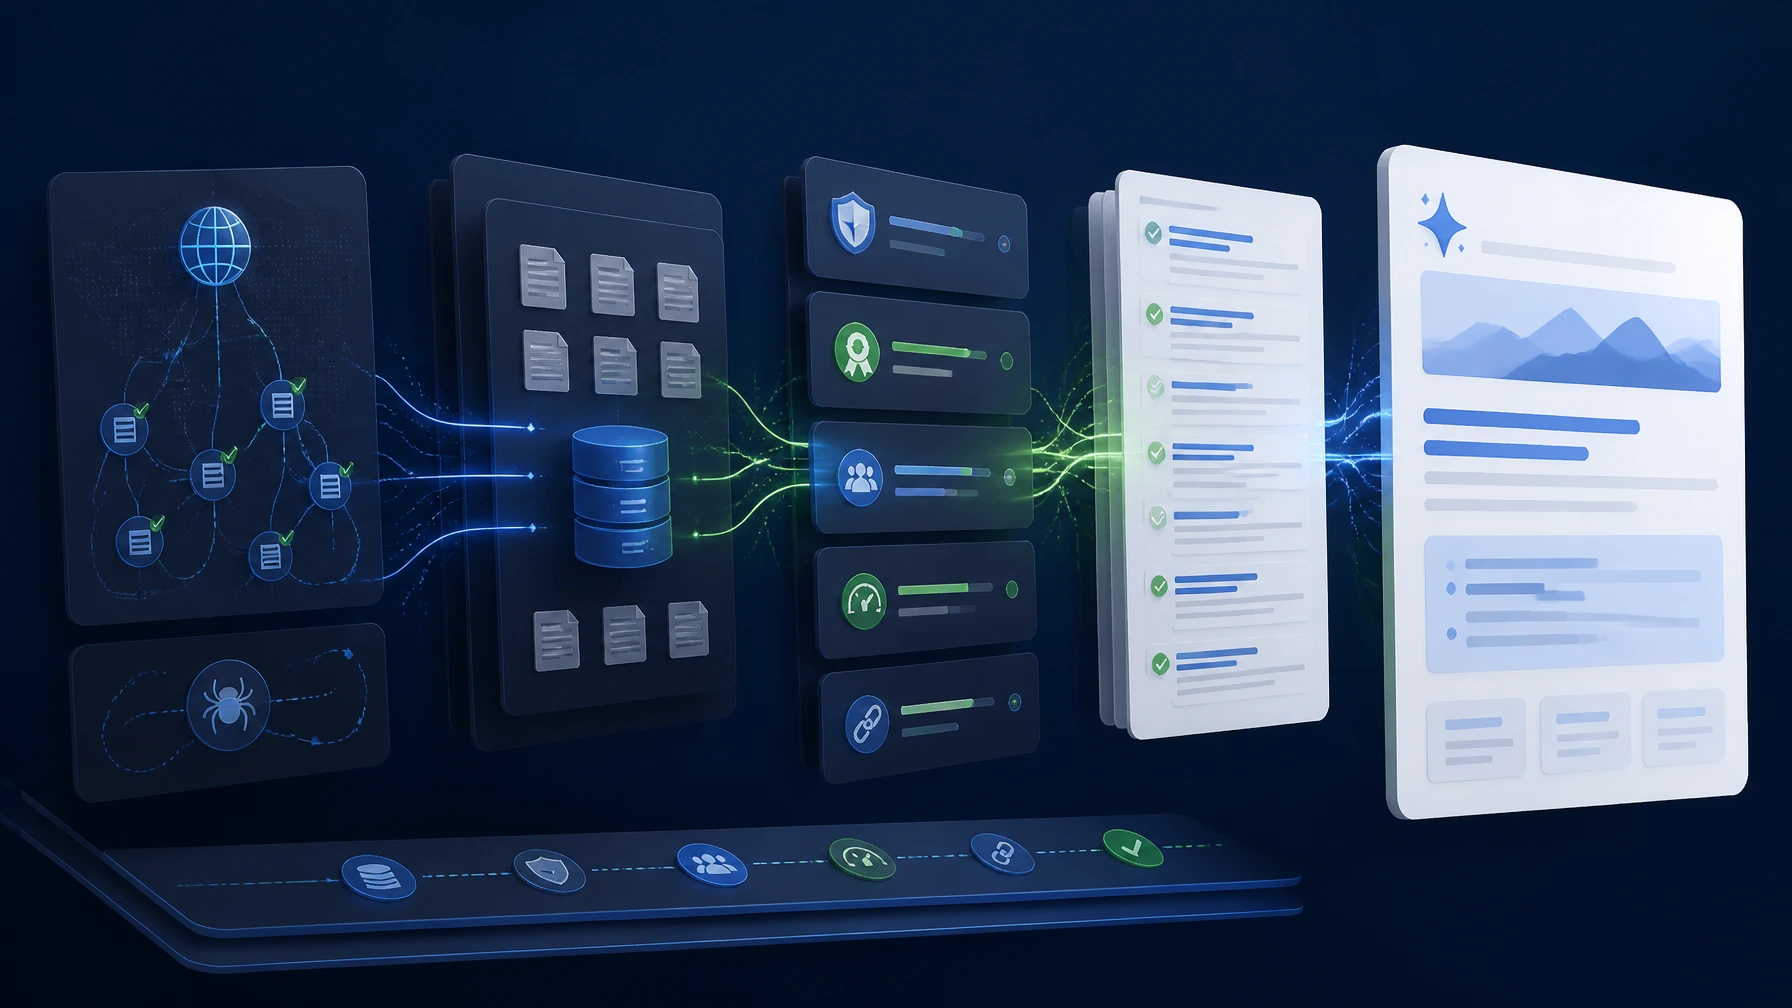
Google's generative optimization guide, updated July 10, 2026, should be read alongside its AI-feature documentation. A supporting page must be indexed and eligible for a snippet. Meeting that baseline does not guarantee selection.
The guidance describes retrieval and related-query fan-out. A useful page can address a decision and its relevant subquestions without repeating every possible formulation. Producing numerous variations principally to manipulate search or generative answers can fall under scaled-content abuse.
Check the URL's status, canonical, indexability and internal links. Confirm that important information is available in text and that infrastructure permits the intended access. External prompt samples can reveal questions to investigate, without exposing Google's internal ranking systems.
Original value with visible evidence
Evaluate what the reader learns beyond another summary of the same sources. A reproducible method, original observation or carefully bounded comparison can supply that value. Preserve the source, dates and conditions that allow someone to check the conclusion.
Separate confirmed product statements from editorial interpretation. An implementation detail needs its actual evidence, while an external statistic needs the originating study. A first-person claim or infographic number alone cannot establish experience or accuracy.
Consolidate sections that repeat the same argument. Retain distinct evidence even when a shorter version would look tidier. Content length should serve the task and its explanation, rather than a supposed extraction quota.
Tactics the guide rejects
Google says special AI text files such as llms.txt are unnecessary for Search. A file maintained for another service is not a Google eligibility requirement. Special AI schema likewise has no documented role here, while ordinary structured data must match visible facts and applicable search-feature policies.
The guide rejects artificial chunking as a required optimization and warns against inauthentic mentions. Synonym and meaning matching do not require publishing every long-tail phrasing as another page. Legitimate reputation and original information still need actual sources.
This leaves room for citation analysis and prompt research as diagnostic work. The limitation is their claim of certainty. They can identify missing information or recurring sources without guaranteeing inclusion or overriding access and quality requirements.
A usable journey for people and agents
The linked web.dev agent-friendly UX guidance describes agents using screenshots, HTML and accessibility information. Semantic buttons and links, labels associated with fields and stable state feedback reduce ambiguity in an action flow.
Test keyboard and mobile behavior as well as visual appearance. Avoid transparent overlays blocking controls and keep names and states consistent. A saved form, booking or purchase should produce an observable confirmation. These are product checks, without being a confirmed ranking factor or a promise that an agent will complete every action.
A thirty-day review
During the first week, validate access, canonicals and important rendered content on existing priority pages. Next, inspect the evidence behind consequential claims. Use the third week to test forms, comparisons and follow-up tasks. In the fourth, compare exposure and outcomes under consistent definitions.
The current generative report help documents worldwide availability from August 31, 2026 and impression-only reporting. Keep official impressions, sampled citations, clicks and conversions separate. Unknown attribution should remain unknown.
An appropriate result is a more defensible inventory and a tested user journey. The documentation review provides the eligibility detail and the query-augmentation review connects distinct decisions to page architecture.
Use mythbusting to remove unnecessary work
The absence of a special Google AI file requirement is a practical prioritization decision. A team can maintain llms.txt for a separate documented use, but should not put it ahead of an inaccessible core page on the theory that it unlocks Search. The same applies to invented AI schema: identify the supported search feature and visible facts before adding markup.
Clear sections remain useful without forced chunking. A reader should be able to locate an answer and understand its conditions. A method that needs several steps should retain them. Splitting every paragraph into a separate page or rewriting the same explanation for every synonym can increase maintenance without supplying additional evidence.
Artificial mentions are a different problem from legitimate distribution. An actual professional reference or independent review can help a reader verify identity. A network of copied promotional claims does not become independent corroboration because it appears on several domains.
A concrete evidence upgrade
Choose one consequential statement on a priority page. Identify whether it is a product fact, external research, a calculation or an observed case. Attach the appropriate evidence: current product documentation, the original study with its sample, visible arithmetic or the actual observation record.
If the evidence is missing, qualify or remove the claim. If the evidence exists but the wording overreaches it, narrow the sentence. Preserve the details necessary to interpret it. For example, a provider experiment can support a result under its conditions without becoming a forecast for every customer. A clearer claim may require a longer explanation than the unsupported slogan it replaces.
Test an action with semantic controls and visible states
The web.dev guidance treats the interface as something agents may interpret through several representations. A button should be an actual button with an understandable name. A link should have a meaningful destination. A form field needs a label associated with it, and an error should identify what must change.
Walk through the task by keyboard and on mobile. Check focus, overlays, disabled controls and the transition after submission. A loading state should not look like completion. If validation fails, the user should understand the error and retain appropriate entered information. Test the final confirmation rather than treating the button click as success.
These checks serve users directly. They are not a disclosed ranking factor or proof that every agent can execute the task. An authenticated operation also requires the business's permissions and user authorization. Semantic HTML does not grant either.
Thirty days of specific deliverables
Week one: entry-point evidence. Save responses, indexability and canonical checks for priority pages. Identify missing main content and broken discovery routes. Give each issue a URL and owner.
Week two: proof. Review consequential statements and add or correct methods, sources and limits. Keep a list of unresolved claims that must remain out. Verify that graphics and structured data do not contradict the corrected explanation.
Week three: task completion. Test the actual comparison, enquiry, calculation or purchase path. Record the stage reached and the failure condition. A useful page with a broken next step still has a product problem.
Week four: measurement. Compare eligible first-party impressions, the stable answer sample and observed outcomes separately. Preserve source delays, sample changes and missing data. Do not merge them into an invented universal AI traffic metric.
Decide the next change from a demonstrated gap
If a page is not eligible, resolve the technical cause. If it is eligible but lacks evidence, improve the evidence. If visitors arrive but cannot complete the task, fix the journey. If all checks pass and the citation sample remains variable, retain that uncertainty instead of adding more files or near-duplicate pages.
The resulting plan is an interpretation of documented guidance and observed site conditions. It does not require a claim about permanent agent capabilities, geopolitical differences or personal implementation history to be actionable.
Frequently Asked Questions
What should a semantic interface test check?
Labels, real links and buttons, keyboard focus, error handling, mobile behavior and final confirmation. A loading state or click alone does not establish completion.
What is a useful evidence upgrade?
Identify the claim type and attach its appropriate source, method or arithmetic. Narrow unsupported wording while retaining conditions that change the recommendation.
Does agent-friendly UX guarantee higher ranking?
No. The UX guidance helps test task completion and accessibility, without establishing a ranking promise.
Should every fan-out wording get a separate URL?
No. Cover distinct decisions and avoid repetitive pages created principally to manipulate results.
About the Author